Data science is a competitive field, and creating a resume that helps you stand out can be tough.
Below, we break down the process of writing a data science resume from scratch.
Alternatively, use our data science resume templates from real candidates.
We'll help you:
Write a resume that attracts more interviews, whether you're a junior or senior data scientist.
Highlight the most relevant projects that align with the goals of the role you're applying for.
👋
Need help with your data science resume? Get your resume reviewed by real data science talent managers at top companies and startups.
This guide was written by Alex Reyes, an Aced career coach, resume coach, and senior technical recruiter with 20+ years of experience.
6 real Data Scientist resumes that passed screening
Browse 303 Data Scientist resumes that candidates used to pass screenings and land interviews at companies like OpenAI, Anthropic, Google, Meta and more.
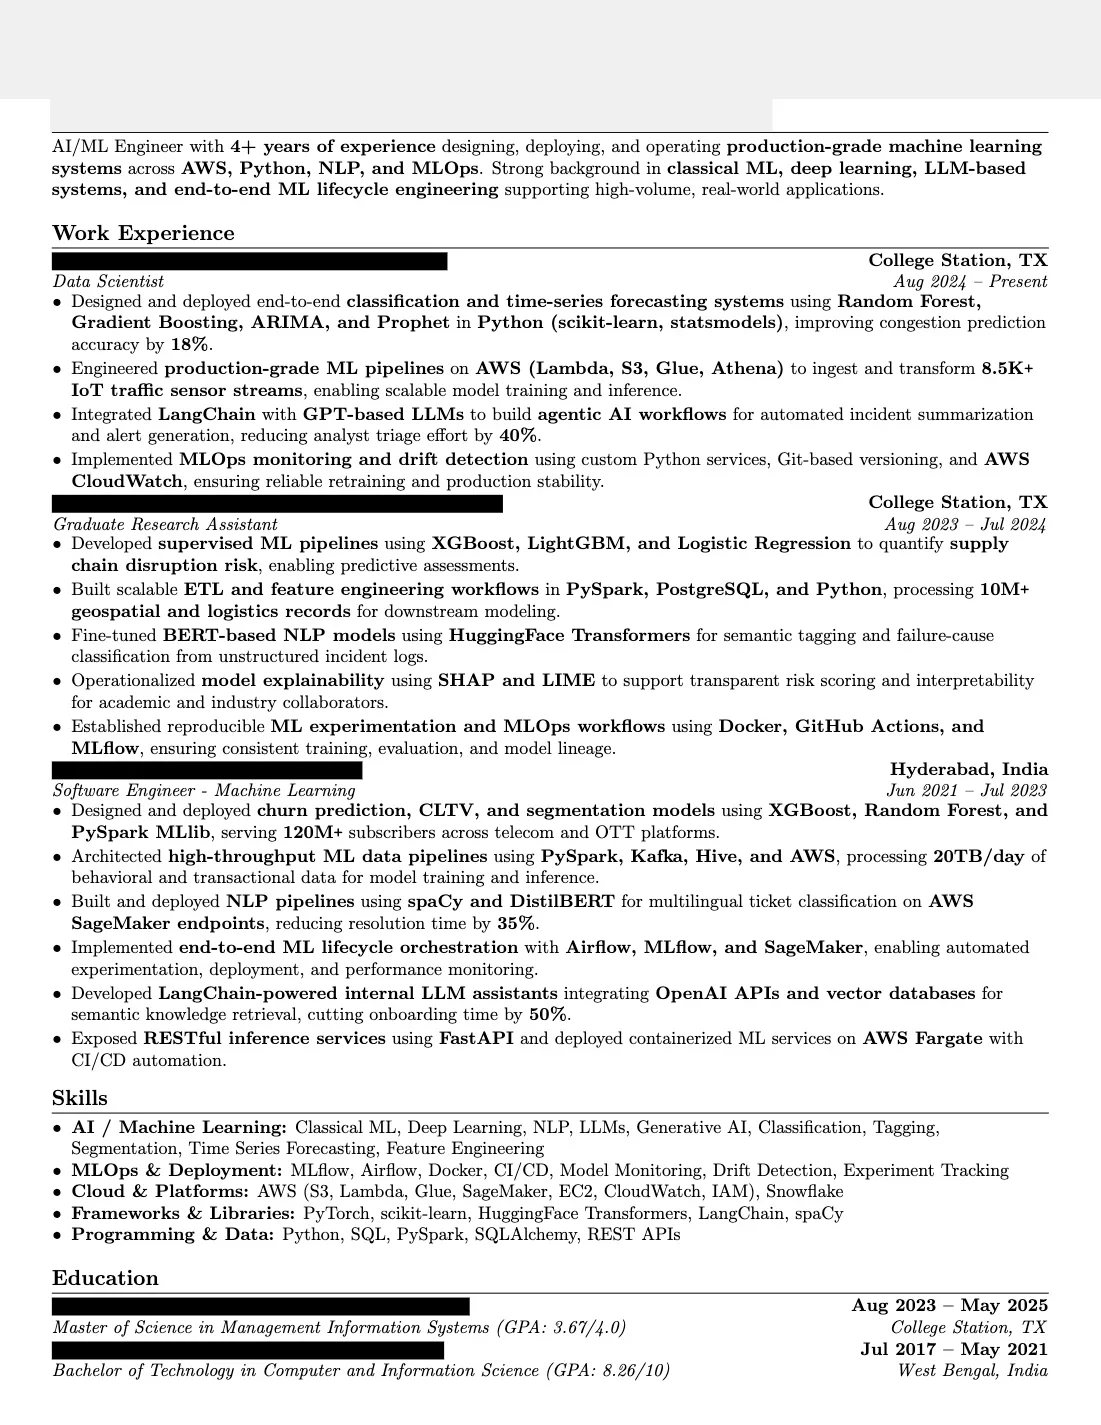
Data scientist with machine learning engineering and MLOps experience
Data Scientist resume that passed screening at Apple, Red Hat and Centerfield. Verified that this candidate landed the interview. Personal details removed.
Three roles, each naming the model types and tools inside the bullet, so a reader matching a job description finds Random Forest, ARIMA, PySpark or SageMaker in context rather than only in a skills list. The LLM work reads as a production workflow with a measured effect: analyst triage effort down 40%.
Lines worth borrowing
Integrated LangChain with GPT-based LLMs to build agentic AI workflows for automated incident summarization and alert generation, reducing analyst triage effort by 40%.
Designed and deployed churn prediction, CLTV, and segmentation models using XGBoost, Random Forest, and PySpark MLlib, serving 120M+ subscribers across telecom and OTT platforms.
Read this Data Scientist resume as text
Transcribed from the resume above. Names, contact details, employers and schools are left out.
Summary
AI/ML Engineer with 4+ years of experience designing, deploying, and operating production-grade machine learning systems across AWS, Python, NLP, and MLOps. Strong background in classical ML, deep learning, LLM-based systems, and end-to-end ML lifecycle engineering supporting high-volume, real-world applications.
Work experience
Data Scientist, [Redacted] · Aug 2024 – present
Designed and deployed end-to-end classification and time-series forecasting systems using Random Forest, Gradient Boosting, ARIMA, and Prophet in Python (scikit-learn, statsmodels), improving congestion prediction accuracy by 18%.
Engineered production-grade ML pipelines on AWS (Lambda, S3, Glue, Athena) to ingest and transform 8.5K+ IoT traffic sensor streams, enabling scalable model training and inference.
Integrated LangChain with GPT-based LLMs to build agentic AI workflows for automated incident summarization and alert generation, reducing analyst triage effort by 40%.
Implemented MLOps monitoring and drift detection using custom Python services, Git-based versioning, and AWS CloudWatch, ensuring reliable retraining and production stability.
Graduate Research Assistant, [Redacted] · Aug 2023 – Jul 2024
Developed supervised ML pipelines using XGBoost, LightGBM, and Logistic Regression to quantify supply chain disruption risk, enabling predictive assessments.
Built scalable ETL and feature engineering workflows in PySpark, PostgreSQL, and Python, processing 10M+ geospatial and logistics records for downstream modeling.
Fine-tuned BERT-based NLP models using HuggingFace Transformers for semantic tagging and failure-cause classification from unstructured incident logs.
Operationalized model explainability using SHAP and LIME to support transparent risk scoring and interpretability for academic and industry collaborators.
Established reproducible ML experimentation and MLOps workflows using Docker, GitHub Actions, and MLflow, ensuring consistent training, evaluation, and model lineage.
Designed and deployed churn prediction, CLTV, and segmentation models using XGBoost, Random Forest, and PySpark MLlib, serving 120M+ subscribers across telecom and OTT platforms.
Architected high-throughput ML data pipelines using PySpark, Kafka, Hive, and AWS, processing 20TB/day of behavioral and transactional data for model training and inference.
Built and deployed NLP pipelines using spaCy and DistilBERT for multilingual ticket classification on AWS SageMaker endpoints, reducing resolution time by 35%.
Implemented end-to-end ML lifecycle orchestration with Airflow, MLflow, and SageMaker, enabling automated experimentation, deployment, and performance monitoring.
Developed LangChain-powered internal LLM assistants integrating OpenAI APIs and vector databases for semantic knowledge retrieval, cutting onboarding time by 50%.
Exposed RESTful inference services using FastAPI and deployed containerized ML services on AWS Fargate with CI/CD automation.
Skills
AI / machine learning: Classical ML, Deep Learning, NLP, LLMs, Generative AI, Classification, Tagging, Segmentation, Time Series Forecasting, Feature Engineering
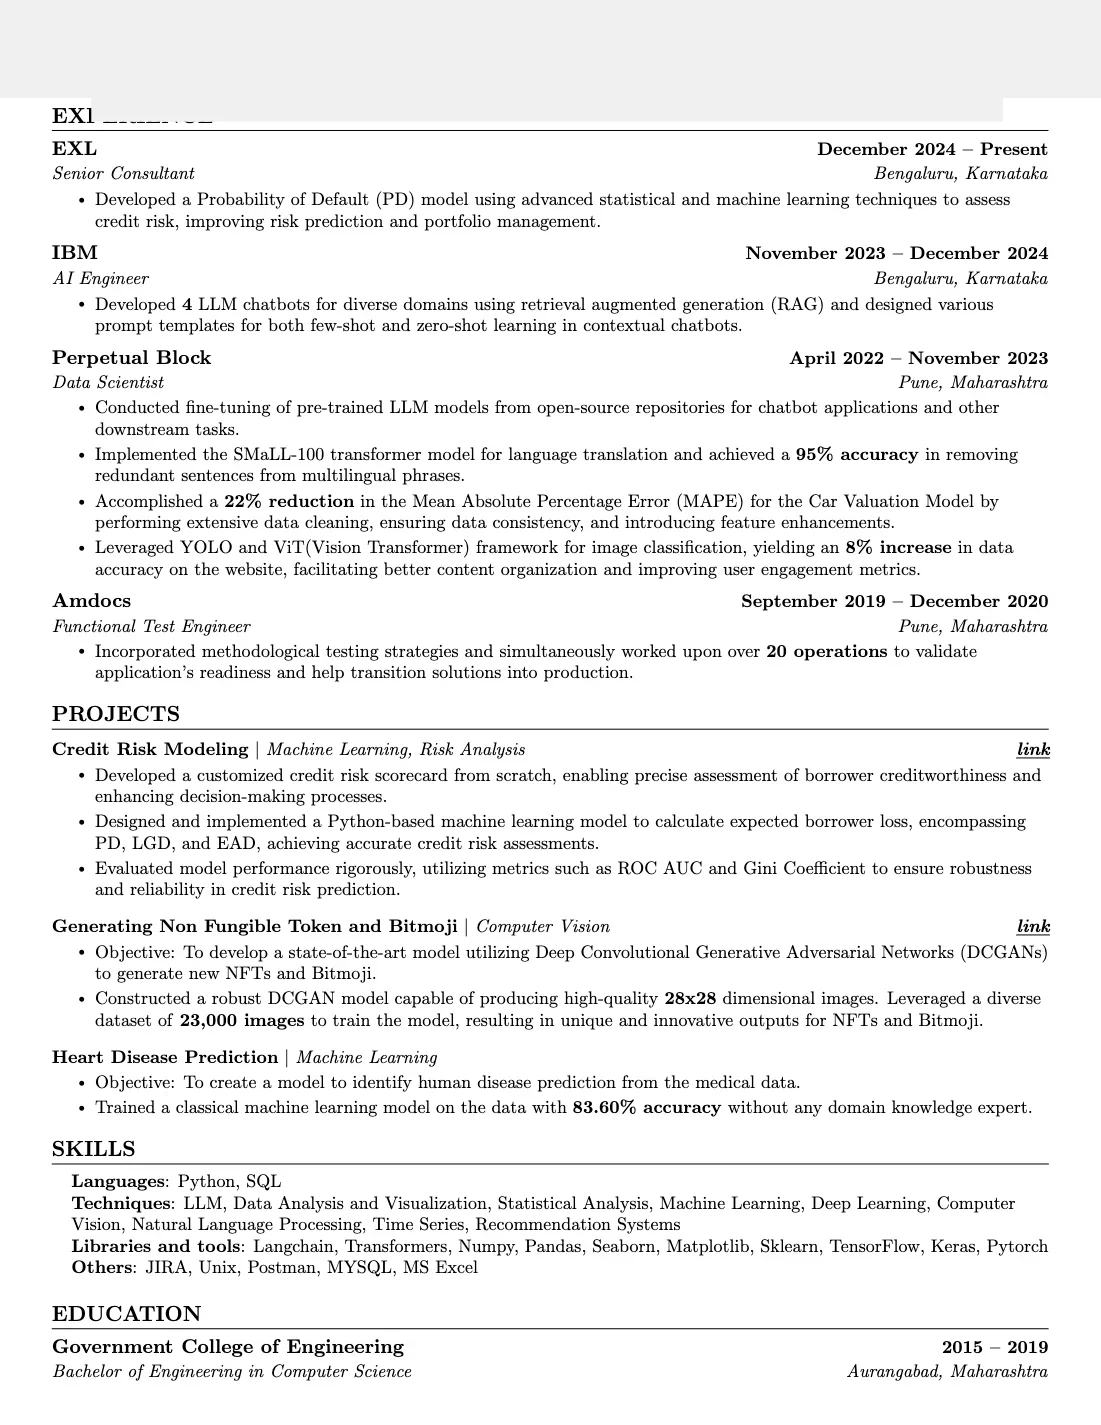
The jobs get one to four bullets each, and the projects fill in the depth: the credit risk project shows the modeling (PD, LGD and EAD, judged by ROC AUC and Gini) that the current consulting role names only in passing. Bullets with a result give the method and the metric together, such as a 22% drop in MAPE from data cleaning and feature work.
Lines worth borrowing
Accomplished a 22% reduction in the Mean Absolute Percentage Error (MAPE) for the Car Valuation Model by performing extensive data cleaning, ensuring data consistency, and introducing feature enhancements.
Designed and implemented a Python-based machine learning model to calculate expected borrower loss, encompassing PD, LGD, and EAD, achieving accurate credit risk assessments.
Read this Data Scientist resume as text
Transcribed from the resume above. Names, contact details, employers and schools are left out.
Experience
Senior Consultant, [Analytics consulting firm] · December 2024 – present
Developed a Probability of Default (PD) model using advanced statistical and machine learning techniques to assess credit risk, improving risk prediction and portfolio management.
AI Engineer, [Large tech company] · November 2023 – December 2024
Developed 4 LLM chatbots for diverse domains using retrieval augmented generation (RAG) and designed various prompt templates for both few-shot and zero-shot learning in contextual chatbots.
Data Scientist, [Startup] · April 2022 – November 2023
Conducted fine-tuning of pre-trained LLM models from open-source repositories for chatbot applications and other downstream tasks.
Implemented the SMaLL-100 transformer model for language translation and achieved a 95% accuracy in removing redundant sentences from multilingual phrases.
Accomplished a 22% reduction in the Mean Absolute Percentage Error (MAPE) for the Car Valuation Model by performing extensive data cleaning, ensuring data consistency, and introducing feature enhancements.
Leveraged YOLO and ViT (Vision Transformer) framework for image classification, yielding an 8% increase in data accuracy on the website, facilitating better content organization and improving user engagement metrics.
Functional Test Engineer, [Software company] · September 2019 – December 2020
Incorporated methodological testing strategies and simultaneously worked upon over 20 operations to validate application's readiness and help transition solutions into production.
Developed a customized credit risk scorecard from scratch, enabling precise assessment of borrower creditworthiness and enhancing decision-making processes.
Designed and implemented a Python-based machine learning model to calculate expected borrower loss, encompassing PD, LGD, and EAD, achieving accurate credit risk assessments.
Evaluated model performance rigorously, utilizing metrics such as ROC AUC and Gini Coefficient to ensure robustness and reliability in credit risk prediction.
Generating Non Fungible Token and Bitmoji (Computer Vision)
Objective: To develop a state-of-the-art model utilizing Deep Convolutional Generative Adversarial Networks (DCGANs) to generate new NFTs and Bitmoji.
Constructed a robust DCGAN model capable of producing high-quality 28x28 dimensional images. Leveraged a diverse dataset of 23,000 images to train the model, resulting in unique and innovative outputs for NFTs and Bitmoji.
Heart Disease Prediction (Machine Learning)
Objective: To create a model to identify human disease prediction from the medical data.
Trained a classical machine learning model on the data with 83.60% accuracy without any domain knowledge expert.
Skills
Languages: Python, SQL
Techniques: LLM, Data Analysis and Visualization, Statistical Analysis, Machine Learning, Deep Learning, Computer Vision, Natural Language Processing, Time Series, Recommendation Systems
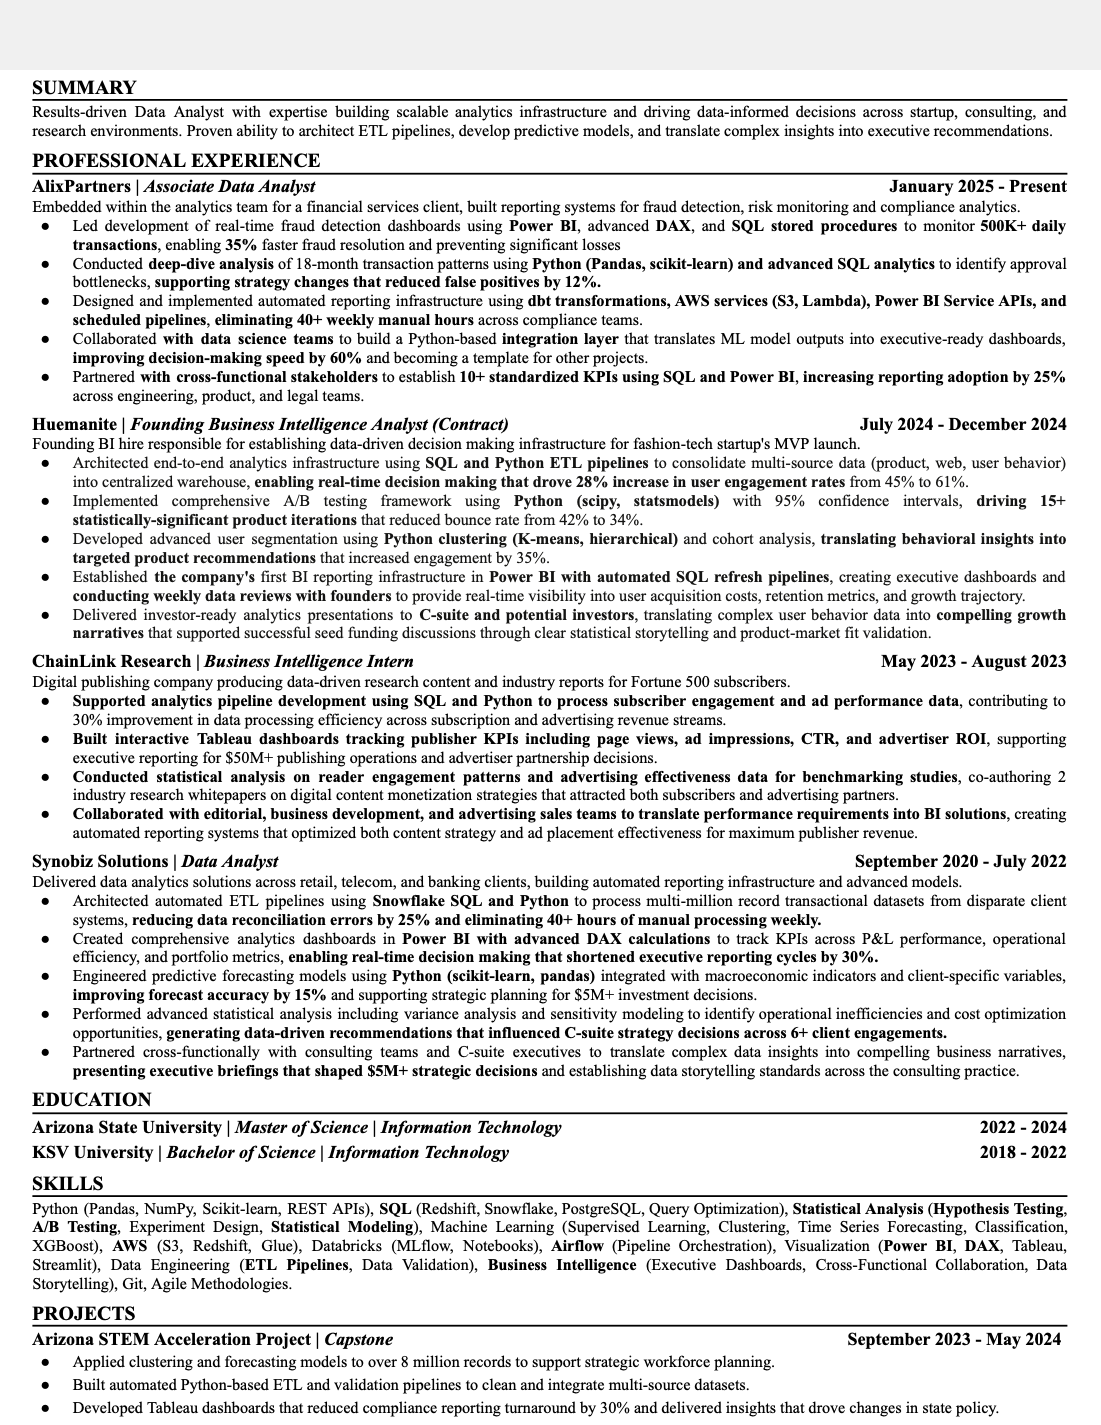
Each role opens with a one-line description of the employer and the team, which saves a reader guessing what an unfamiliar company does. The startup role is where the data science shows: an A/B testing framework, clustering for segmentation, and before-and-after numbers such as bounce rate from 42% to 34%. It doubles as a model for a data analyst resume.
Lines worth borrowing
Implemented comprehensive A/B testing framework using Python (scipy, statsmodels) with 95% confidence intervals, driving 15+ statistically-significant product iterations that reduced bounce rate from 42% to 34%.
Developed advanced user segmentation using Python clustering (K-means, hierarchical) and cohort analysis, translating behavioral insights into targeted product recommendations that increased engagement by 35%.
Conducted deep-dive analysis of 18-month transaction patterns using Python (Pandas, scikit-learn) and advanced SQL analytics to identify approval bottlenecks, supporting strategy changes that reduced false positives by 12%.
Read this Data Scientist resume as text
Transcribed from the resume above. Names, contact details, employers and schools are left out.
Summary
Results-driven Data Analyst with expertise building scalable analytics infrastructure and driving data-informed decisions across startup, consulting, and research environments. Proven ability to architect ETL pipelines, develop predictive models, and translate complex insights into executive recommendations.
Professional experience
Associate Data Analyst, [Consulting firm] · January 2025 – present
Embedded within the analytics team for a financial services client, built reporting systems for fraud detection, risk monitoring and compliance analytics.
Led development of real-time fraud detection dashboards using Power BI, advanced DAX, and SQL stored procedures to monitor 500K+ daily transactions, enabling 35% faster fraud resolution and preventing significant losses
Conducted deep-dive analysis of 18-month transaction patterns using Python (Pandas, scikit-learn) and advanced SQL analytics to identify approval bottlenecks, supporting strategy changes that reduced false positives by 12%.
Designed and implemented automated reporting infrastructure using dbt transformations, AWS services (S3, Lambda), Power BI Service APIs, and scheduled pipelines, eliminating 40+ weekly manual hours across compliance teams.
Collaborated with data science teams to build a Python-based integration layer that translates ML model outputs into executive-ready dashboards, improving decision-making speed by 60% and becoming a template for other projects.
Partnered with cross-functional stakeholders to establish 10+ standardized KPIs using SQL and Power BI, increasing reporting adoption by 25% across engineering, product, and legal teams.
Founding Business Intelligence Analyst (Contract), [Fashion-tech startup] · July 2024 – December 2024
Founding BI hire responsible for establishing data-driven decision making infrastructure for fashion-tech startup's MVP launch.
Architected end-to-end analytics infrastructure using SQL and Python ETL pipelines to consolidate multi-source data (product, web, user behavior) into centralized warehouse, enabling real-time decision making that drove 28% increase in user engagement rates from 45% to 61%.
Implemented comprehensive A/B testing framework using Python (scipy, statsmodels) with 95% confidence intervals, driving 15+ statistically-significant product iterations that reduced bounce rate from 42% to 34%.
Developed advanced user segmentation using Python clustering (K-means, hierarchical) and cohort analysis, translating behavioral insights into targeted product recommendations that increased engagement by 35%.
Established the company's first BI reporting infrastructure in Power BI with automated SQL refresh pipelines, creating executive dashboards and conducting weekly data reviews with founders to provide real-time visibility into user acquisition costs, retention metrics, and growth trajectory.
Delivered investor-ready analytics presentations to C-suite and potential investors, translating complex user behavior data into compelling growth narratives that supported successful seed funding discussions through clear statistical storytelling and product-market fit validation.
Business Intelligence Intern, [Research publisher] · May 2023 – August 2023
Digital publishing company producing data-driven research content and industry reports for Fortune 500 subscribers.
Supported analytics pipeline development using SQL and Python to process subscriber engagement and ad performance data, contributing to 30% improvement in data processing efficiency across subscription and advertising revenue streams.
Built interactive Tableau dashboards tracking publisher KPIs including page views, ad impressions, CTR, and advertiser ROI, supporting executive reporting for $50M+ publishing operations and advertiser partnership decisions.
Conducted statistical analysis on reader engagement patterns and advertising effectiveness data for benchmarking studies, co-authoring 2 industry research whitepapers on digital content monetization strategies that attracted both subscribers and advertising partners.
Collaborated with editorial, business development, and advertising sales teams to translate performance requirements into BI solutions, creating automated reporting systems that optimized both content strategy and ad placement effectiveness for maximum publisher revenue.
Data Analyst, [IT services company] · September 2020 – July 2022
Delivered data analytics solutions across retail, telecom, and banking clients, building automated reporting infrastructure and advanced models.
Architected automated ETL pipelines using Snowflake SQL and Python to process multi-million record transactional datasets from disparate client systems, reducing data reconciliation errors by 25% and eliminating 40+ hours of manual processing weekly.
Created comprehensive analytics dashboards in Power BI with advanced DAX calculations to track KPIs across P&L performance, operational efficiency, and portfolio metrics, enabling real-time decision making that shortened executive reporting cycles by 30%.
Engineered predictive forecasting models using Python (scikit-learn, pandas) integrated with macroeconomic indicators and client-specific variables, improving forecast accuracy by 15% and supporting strategic planning for $5M+ investment decisions.
Performed advanced statistical analysis including variance analysis and sensitivity modeling to identify operational inefficiencies and cost optimization opportunities, generating data-driven recommendations that influenced C-suite strategy decisions across 6+ client engagements.
Partnered cross-functionally with consulting teams and C-suite executives to translate complex data insights into compelling business narratives, presenting executive briefings that shaped $5M+ strategic decisions and establishing data storytelling standards across the consulting practice.
Education
Master of Science, Information Technology, [University] · 2022 – 2024
Bachelor of Science, Information Technology, [University] · 2018 – 2022
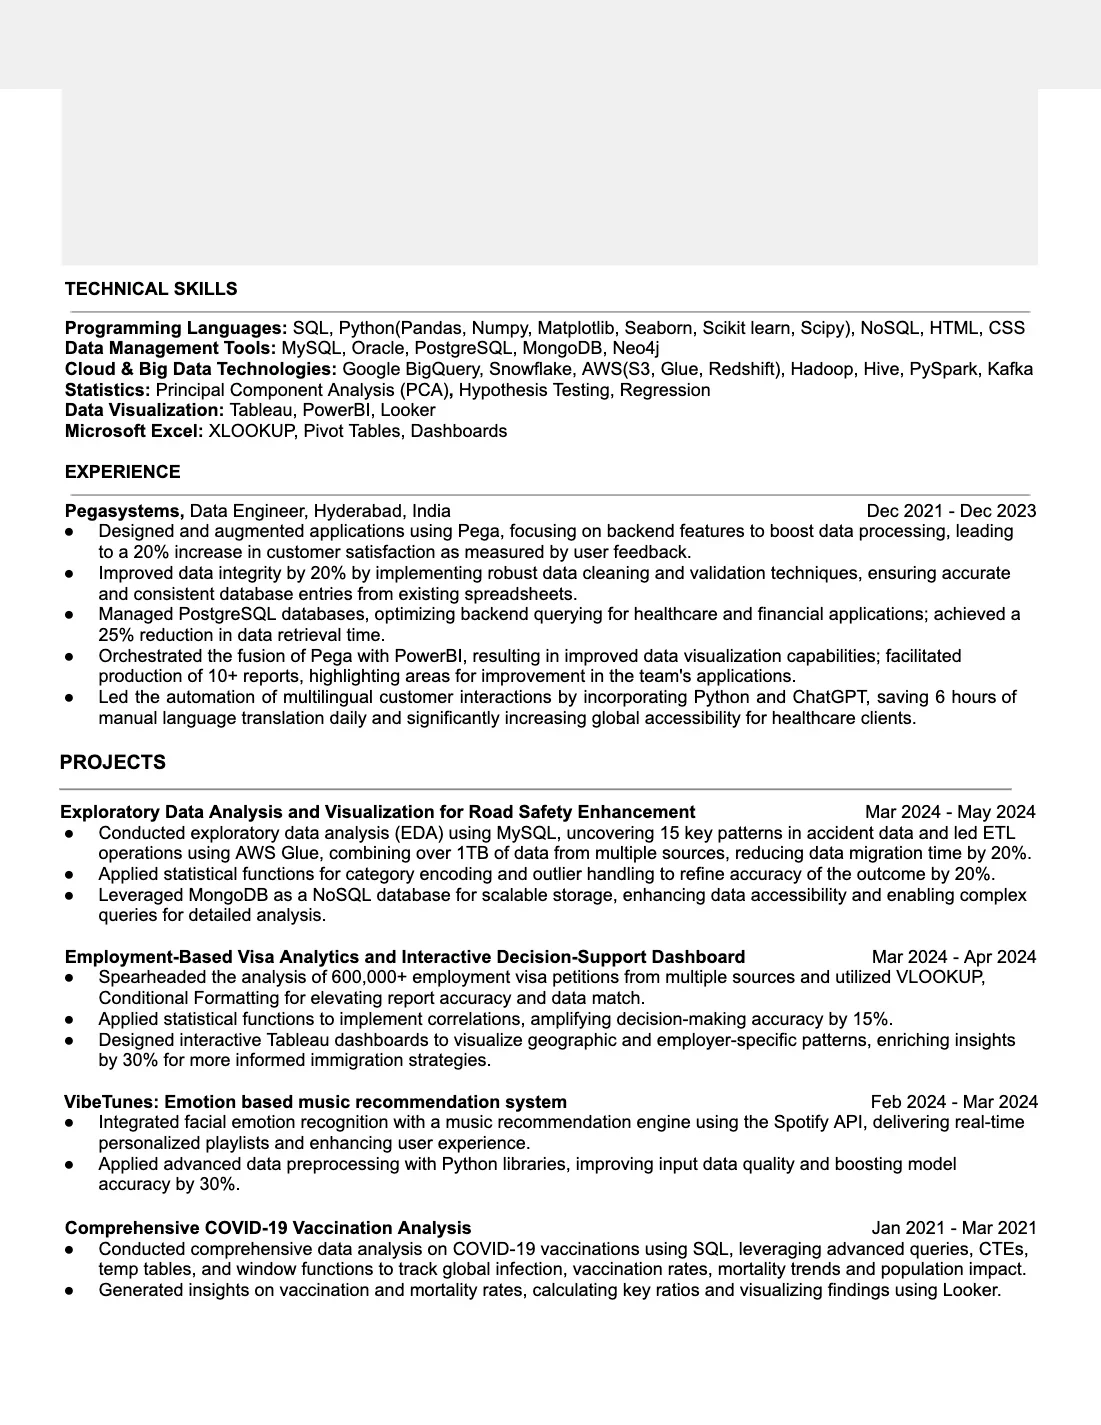
One data engineering job, then four analysis projects on public data (accident records, visa petitions, vaccination figures). That is how this resume shows the statistics and modeling the job did not cover. The skills section comes first and is grouped by type, so SQL, Python libraries, cloud tools and statistical methods are each easy to find.
Lines worth borrowing
Spearheaded the analysis of 600,000+ employment visa petitions from multiple sources and utilized VLOOKUP, Conditional Formatting for elevating report accuracy and data match.
Led the automation of multilingual customer interactions by incorporating Python and ChatGPT, saving 6 hours of manual language translation daily and significantly increasing global accessibility for healthcare clients.
Read this Data Scientist resume as text
Transcribed from the resume above. Names, contact details, employers and schools are left out.
Data Management Tools: MySQL, Oracle, PostgreSQL, MongoDB, Neo4j
Cloud & Big Data Technologies: Google BigQuery, Snowflake, AWS (S3, Glue, Redshift), Hadoop, Hive, PySpark, Kafka
Statistics: Principal Component Analysis (PCA), Hypothesis Testing, Regression
Data Visualization: Tableau, PowerBI, Looker
Microsoft Excel: XLOOKUP, Pivot Tables, Dashboards
Experience
Data Engineer, [Enterprise software company] · Dec 2021 – Dec 2023
Designed and augmented applications using Pega, focusing on backend features to boost data processing, leading to a 20% increase in customer satisfaction as measured by user feedback.
Improved data integrity by 20% by implementing robust data cleaning and validation techniques, ensuring accurate and consistent database entries from existing spreadsheets.
Managed PostgreSQL databases, optimizing backend querying for healthcare and financial applications; achieved a 25% reduction in data retrieval time.
Orchestrated the fusion of Pega with PowerBI, resulting in improved data visualization capabilities; facilitated production of 10+ reports, highlighting areas for improvement in the team's applications.
Led the automation of multilingual customer interactions by incorporating Python and ChatGPT, saving 6 hours of manual language translation daily and significantly increasing global accessibility for healthcare clients.
Projects
Exploratory Data Analysis and Visualization for Road Safety Enhancement · Mar 2024 – May 2024
Conducted exploratory data analysis (EDA) using MySQL, uncovering 15 key patterns in accident data and led ETL operations using AWS Glue, combining over 1TB of data from multiple sources, reducing data migration time by 20%.
Applied statistical functions for category encoding and outlier handling to refine accuracy of the outcome by 20%.
Leveraged MongoDB as a NoSQL database for scalable storage, enhancing data accessibility and enabling complex queries for detailed analysis.
Employment-Based Visa Analytics and Interactive Decision-Support Dashboard · Mar 2024 – Apr 2024
Spearheaded the analysis of 600,000+ employment visa petitions from multiple sources and utilized VLOOKUP, Conditional Formatting for elevating report accuracy and data match.
Applied statistical functions to implement correlations, amplifying decision-making accuracy by 15%.
Designed interactive Tableau dashboards to visualize geographic and employer-specific patterns, enriching insights by 30% for more informed immigration strategies.
Emotion-based music recommendation system · Feb 2024 – Mar 2024
Integrated facial emotion recognition with a music recommendation engine using the Spotify API, delivering real-time personalized playlists and enhancing user experience.
Applied advanced data preprocessing with Python libraries, improving input data quality and boosting model accuracy by 30%.
Comprehensive COVID-19 Vaccination Analysis · Jan 2021 – Mar 2021
Conducted comprehensive data analysis on COVID-19 vaccinations using SQL, leveraging advanced queries, CTEs, temp tables, and window functions to track global infection, vaccination rates, mortality trends and population impact.
Generated insights on vaccination and mortality rates, calculating key ratios and visualizing findings using Looker.
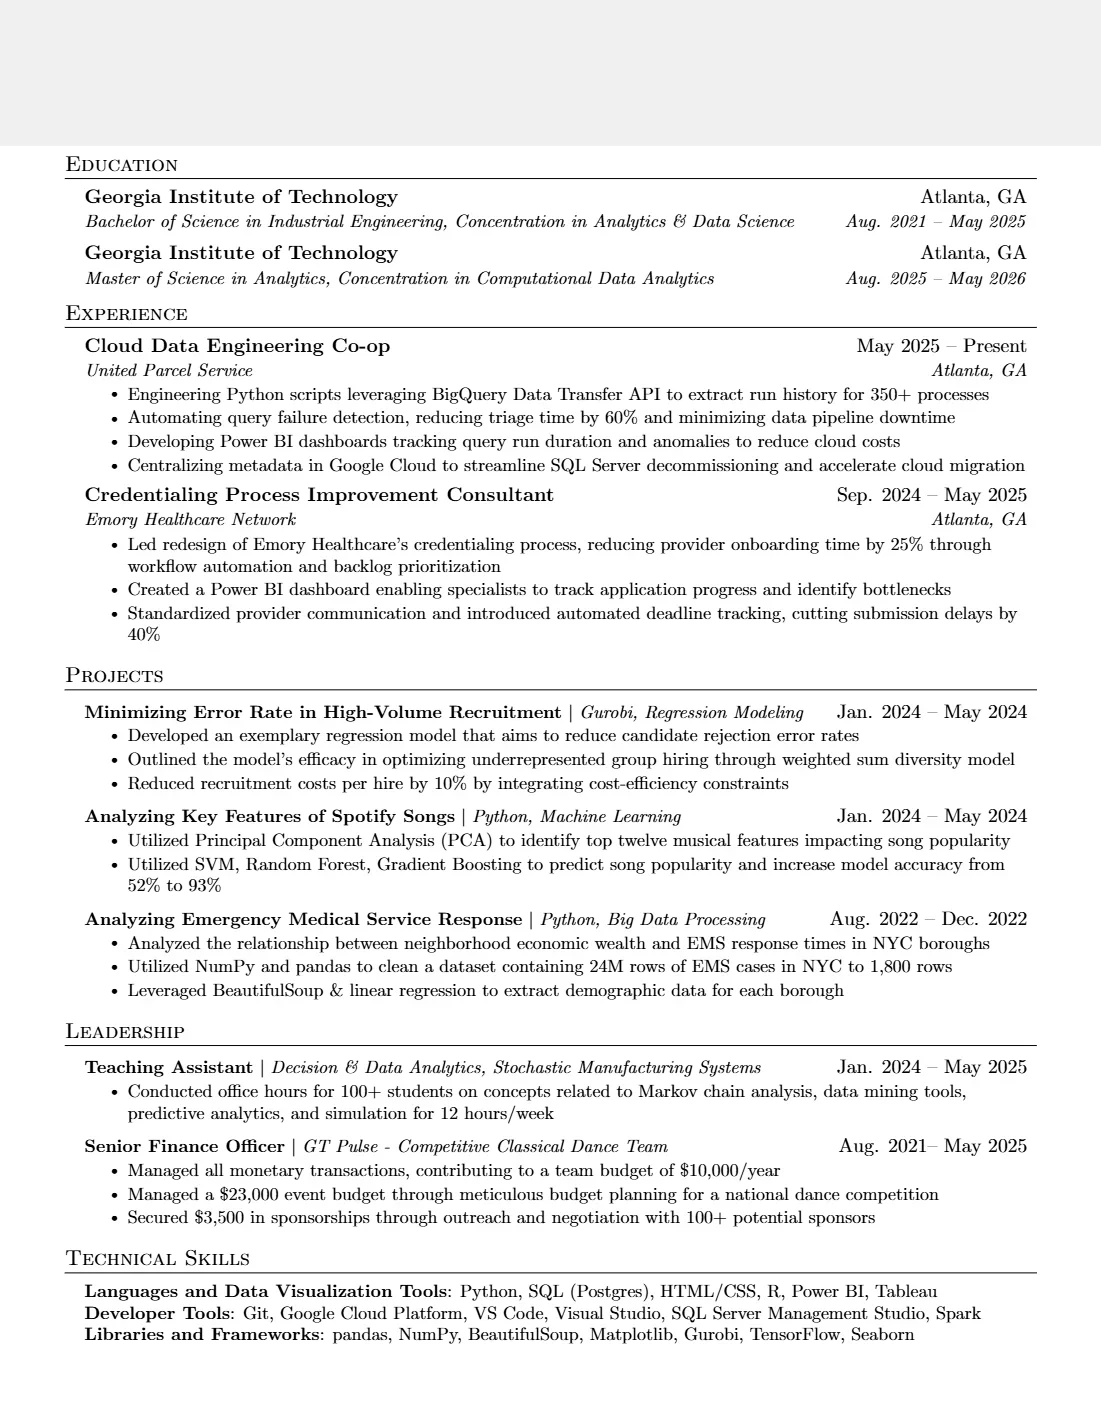
New grad from industrial engineering into a master's in analytics
Data Scientist resume that passed screening at United Parcel Service, Warner Bros and T-Mobile. Verified that this candidate landed the interview. Personal details removed.
Education leads because both degrees carry an analytics concentration. The co-op bullets are short and in the present tense for a current role, and each project names its method in the heading line (Gurobi, regression, machine learning), so a reader sees optimization and modeling next to the data engineering.
Lines worth borrowing
Automating query failure detection, reducing triage time by 60% and minimizing data pipeline downtime
Utilized SVM, Random Forest, Gradient Boosting to predict song popularity and increase model accuracy from 52% to 93%
Read this Data Scientist resume as text
Transcribed from the resume above. Names, contact details, employers and schools are left out.
Education
Bachelor of Science in Industrial Engineering, Concentration in Analytics & Data Science, [University] · Aug. 2021 – May 2025
Master of Science in Analytics, Concentration in Computational Data Analytics, [University] · Aug. 2025 – May 2026
Experience
Cloud Data Engineering Co-op, [Logistics company] · May 2025 – present
Engineering Python scripts leveraging BigQuery Data Transfer API to extract run history for 350+ processes
Automating query failure detection, reducing triage time by 60% and minimizing data pipeline downtime
Developing Power BI dashboards tracking query run duration and anomalies to reduce cloud costs
Centralizing metadata in Google Cloud to streamline SQL Server decommissioning and accelerate cloud migration
Credentialing Process Improvement Consultant, [Healthcare network] · Sep. 2024 – May 2025
Led redesign of [the network]'s credentialing process, reducing provider onboarding time by 25% through workflow automation and backlog prioritization
Created a Power BI dashboard enabling specialists to track application progress and identify bottlenecks
Standardized provider communication and introduced automated deadline tracking, cutting submission delays by 40%
Projects
Minimizing Error Rate in High-Volume Recruitment (Gurobi, Regression Modeling) · Jan. 2024 – May 2024
Developed an exemplary regression model that aims to reduce candidate rejection error rates
Outlined the model's efficacy in optimizing underrepresented group hiring through weighted sum diversity model
Reduced recruitment costs per hire by 10% by integrating cost-efficiency constraints
Analyzing Key Features of Spotify Songs (Python, Machine Learning) · Jan. 2024 – May 2024
Utilized Principal Component Analysis (PCA) to identify top twelve musical features impacting song popularity
Utilized SVM, Random Forest, Gradient Boosting to predict song popularity and increase model accuracy from 52% to 93%
Analyzing Emergency Medical Service Response (Python, Big Data Processing) · Aug. 2022 – Dec. 2022
Analyzed the relationship between neighborhood economic wealth and EMS response times in NYC boroughs
Utilized NumPy and pandas to clean a dataset containing 24M rows of EMS cases in NYC to 1,800 rows
Leveraged BeautifulSoup & linear regression to extract demographic data for each borough
Leadership
Teaching Assistant, Decision & Data Analytics, Stochastic Manufacturing Systems · Jan. 2024 – May 2025
Conducted office hours for 100+ students on concepts related to Markov chain analysis, data mining tools, predictive analytics, and simulation for 12 hours/week
Senior Finance Officer, [Student dance team] · Aug. 2021 – May 2025
Managed all monetary transactions, contributing to a team budget of $10,000/year
Managed a $23,000 event budget through meticulous budget planning for a national dance competition
Secured $3,500 in sponsorships through outreach and negotiation with 100+ potential sponsors
Technical skills
Languages and Data Visualization Tools: Python, SQL (Postgres), HTML/CSS, R, Power BI, Tableau
Developer Tools: Git, Google Cloud Platform, VS Code, Visual Studio, SQL Server Management Studio, Spark
Libraries and Frameworks: pandas, NumPy, BeautifulSoup, Matplotlib, Gurobi, TensorFlow, Seaborn
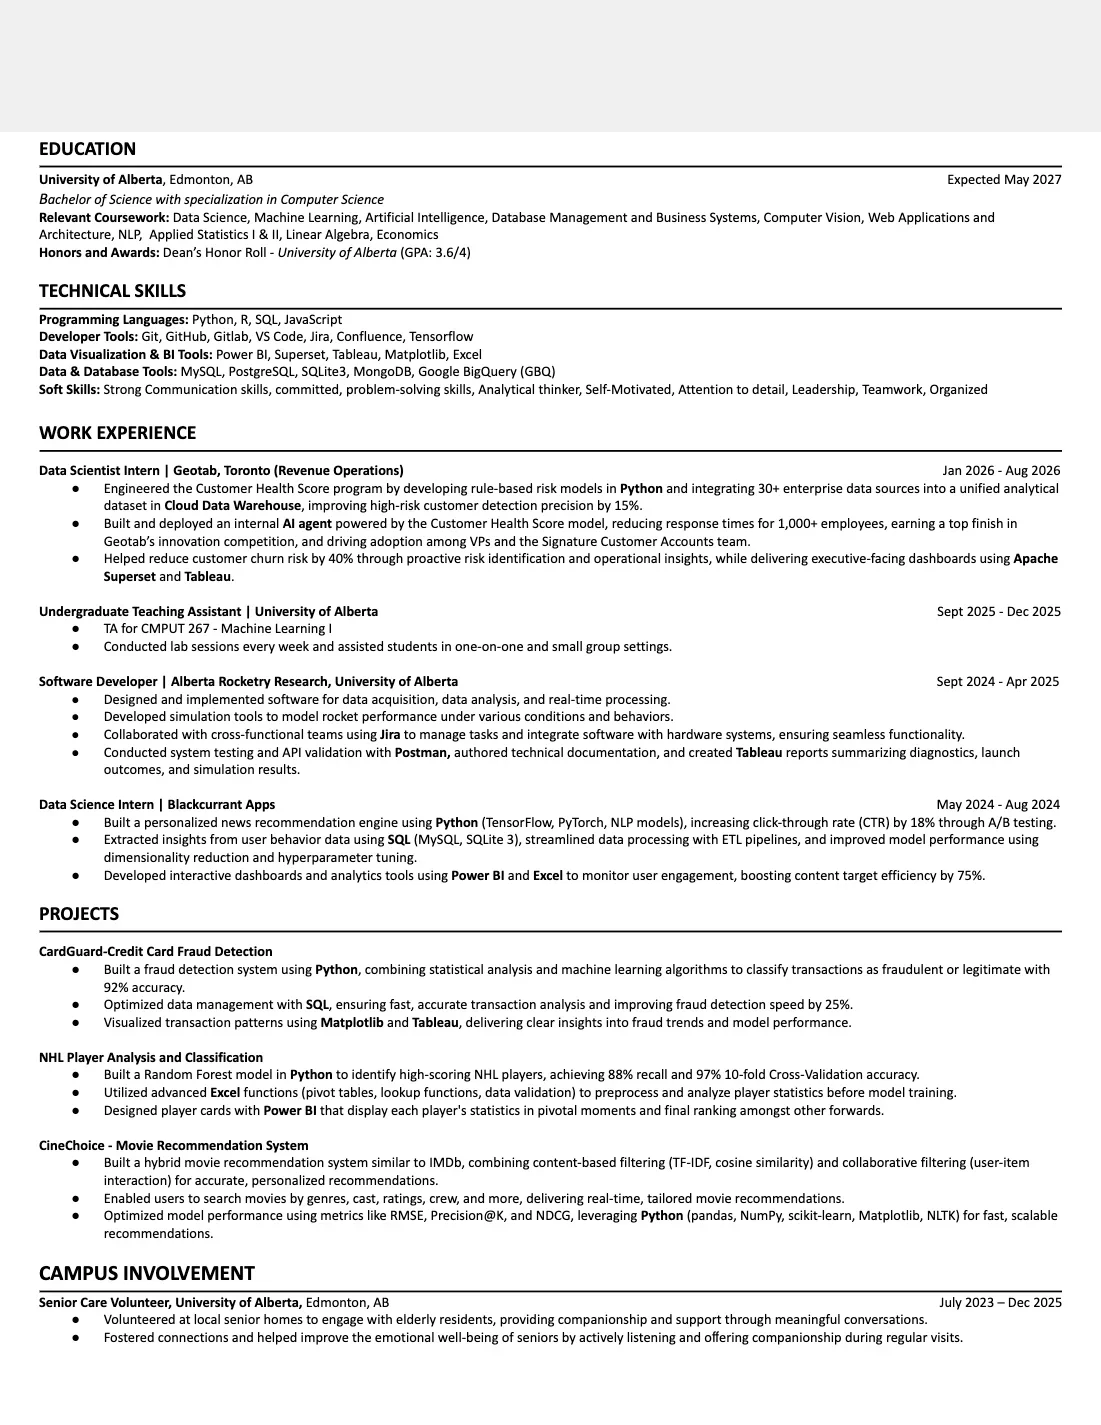
Computer science student with a data science internship
Data Scientist resume that passed screening at Activision Blizzard. Verified that this candidate landed the interview. Personal details removed.
The internship bullets tie each model to a business result: high-risk customer detection precision up 15%, click-through up 18% through A/B testing. Teaching assistant work for a machine learning course and software for a university rocketry team round out a page that would otherwise be mostly projects.
Lines worth borrowing
Engineered the Customer Health Score program by developing rule-based risk models in Python and integrating 30+ enterprise data sources into a unified analytical dataset in Cloud Data Warehouse, improving high-risk customer detection precision by 15%.
Built a personalized news recommendation engine using Python (TensorFlow, PyTorch, NLP models), increasing click-through rate (CTR) by 18% through A/B testing.
Read this Data Scientist resume as text
Transcribed from the resume above. Names, contact details, employers and schools are left out.
Education
Bachelor of Science with specialization in Computer Science, [University] · Expected May 2027
Relevant Coursework: Data Science, Machine Learning, Artificial Intelligence, Database Management and Business Systems, Computer Vision, Web Applications and Architecture, NLP, Applied Statistics I & II, Linear Algebra, Economics. Honors and Awards: Dean's Honor Roll (GPA: 3.6/4)
Technical skills
Programming Languages: Python, R, SQL, JavaScript
Developer Tools: Git, GitHub, Gitlab, VS Code, Jira, Confluence, Tensorflow
Data Visualization & BI Tools: Power BI, Superset, Tableau, Matplotlib, Excel
Data & Database Tools: MySQL, PostgreSQL, SQLite3, MongoDB, Google BigQuery (GBQ)
Soft Skills: Strong Communication skills, committed, problem-solving skills, Analytical thinker, Self-Motivated, Attention to detail, Leadership, Teamwork, Organized
Work experience
Data Scientist Intern (Revenue Operations), [Telematics company] · Jan 2026 – Aug 2026
Engineered the Customer Health Score program by developing rule-based risk models in Python and integrating 30+ enterprise data sources into a unified analytical dataset in Cloud Data Warehouse, improving high-risk customer detection precision by 15%.
Built and deployed an internal AI agent powered by the Customer Health Score model, reducing response times for 1,000+ employees, earning a top finish in [the company]'s innovation competition, and driving adoption among VPs and the [customer accounts] team.
Helped reduce customer churn risk by 40% through proactive risk identification and operational insights, while delivering executive-facing dashboards using Apache Superset and Tableau.
Undergraduate Teaching Assistant, [University] · Sept 2025 – Dec 2025
TA for [an introductory machine learning course]
Conducted lab sessions every week and assisted students in one-on-one and small group settings.
Designed and implemented software for data acquisition, data analysis, and real-time processing.
Developed simulation tools to model rocket performance under various conditions and behaviors.
Collaborated with cross-functional teams using Jira to manage tasks and integrate software with hardware systems, ensuring seamless functionality.
Conducted system testing and API validation with Postman, authored technical documentation, and created Tableau reports summarizing diagnostics, launch outcomes, and simulation results.
Data Science Intern, [App developer] · May 2024 – Aug 2024
Built a personalized news recommendation engine using Python (TensorFlow, PyTorch, NLP models), increasing click-through rate (CTR) by 18% through A/B testing.
Extracted insights from user behavior data using SQL (MySQL, SQLite 3), streamlined data processing with ETL pipelines, and improved model performance using dimensionality reduction and hyperparameter tuning.
Developed interactive dashboards and analytics tools using Power BI and Excel to monitor user engagement, boosting content target efficiency by 75%.
Projects
Credit card fraud detection
Built a fraud detection system using Python, combining statistical analysis and machine learning algorithms to classify transactions as fraudulent or legitimate with 92% accuracy.
Optimized data management with SQL, ensuring fast, accurate transaction analysis and improving fraud detection speed by 25%.
Visualized transaction patterns using Matplotlib and Tableau, delivering clear insights into fraud trends and model performance.
NHL Player Analysis and Classification
Built a Random Forest model in Python to identify high-scoring NHL players, achieving 88% recall and 97% 10-fold Cross-Validation accuracy.
Utilized advanced Excel functions (pivot tables, lookup functions, data validation) to preprocess and analyze player statistics before model training.
Designed player cards with Power BI that display each player's statistics in pivotal moments and final ranking amongst other forwards.
Movie Recommendation System
Built a hybrid movie recommendation system similar to IMDb, combining content-based filtering (TF-IDF, cosine similarity) and collaborative filtering (user-item interaction) for accurate, personalized recommendations.
Enabled users to search movies by genres, cast, ratings, crew, and more, delivering real-time, tailored movie recommendations.
Optimized model performance using metrics like RMSE, Precision at K, and NDCG, leveraging Python (pandas, NumPy, scikit-learn, Matplotlib, NLTK) for fast, scalable recommendations.
Campus involvement
Senior Care Volunteer, [University] · July 2023 – Dec 2025
Volunteered at local senior homes to engage with elderly residents, providing companionship and support through meaningful conversations.
Fostered connections and helped improve the emotional well-being of seniors by actively listening and offering companionship during regular visits.
A well-structured data science resume should have detailed hands-on data experience, highlighted projects and impacts, a technical skills section, and relevant education.
Customizing your resume for each job application is essential. Tailor your summary and role descriptions to align with specific job requirements and company culture. Mapping your accomplishments to the Data Scientist core skills will increase readability and alignment for most job descriptions in the market.
Balancing technical skills with soft skills, such as communication and critical thinking, boosts your resume’s effectiveness.
[Template] Senior Data Scientist (Pinterest)
This template comes from a senior data scientist who landed a Pinterest role.
This is an example of a senior data science resume for Pinterest.
Why this resume works
Quantified Achievements: This resume effectively quantifies accomplishments, such as improving MDG accuracy from 96% to 98.8% and driving a 15% revenue increase at Merkle.
Relevant Technical Skills: The resume showcases the candidate’s proficiency in key tools like SQL, Python, and data analysis techniques.
Project and Tool Integration: The resume integrates projects and tools directly into the work experience descriptions, showing practical, hands-on experience.
[Template] Junior Data Scientist (Apple)
This is an actual resume example from a junior data scientist who landed a job at Apple after working as a data analyst and intern.
This is an example of a junior data science resume for Apple.
Why this resume works
Quantified Achievements: The resume effectively quantifies contributions, such as improving model accuracy and driving a 15% revenue increase. Highlighting these metrics shows the candidate’s work's direct impact.
Project and Tool Integration: By integrating projects with work experience, the resume clearly demonstrates practical data analysis and model development abilities.
Key Elements
Every successful resume should include:
Contact Information: Place your name, location, email, and links to your LinkedIn or GitHub profiles at the top. Keep this section concise—no more than two single-spaced lines.
Professional Summary: Provide a brief overview of your key achievements and skills. Junior candidates should focus on education and relevant projects. This summary should be 3-5 lines, covering who you are, what you do, your major accomplishments, and your next career goal.
Work Experience: Highlight your most relevant roles in reverse chronological order, focusing on measurable achievements.
Projects: Showcase projects that demonstrate your data analysis and modeling skills. Align these projects with the industry and the products or services you’re targeting. As you gain more experience, this section may be streamlined.
Skills Section: Highlight the technical skills and tools relevant to the job. List your most proficient skills first, as hiring managers often assume these are your strongest.
Education: Include your degree(s) and any relevant coursework or certifications, especially if you’re a recent graduate. For experienced candidates, this section should be brief.
Use Reverse-Chronological Order: Start with your most recent work experience.
Keep It Concise: If you have less than five years of experience, aim to keep everything on a single page. Two pages are OK for those with more experience.
Be ATS-Friendly: Use simple formatting and relevant keywords to ensure your resume can pass through Applicant Tracking Systems (ATS) and reach a hiring manager.
Professional Design: Use a clean, professional format with easy-to-read fonts like Arial or Calibri.
Professional Summary
Your data science resume summary should be your personal pitch, summarizing your background and experience in 3 to 5 sentences.
Structure it like this:
Who you are
What you do
What you’re known for (significant career accomplishment)
Where you’re going next (target role - function and/or industry)
For example:
Led, developed, and launched X product into a new market, resulting in X% market adoption rate and $XXX revenue.
Focus on your most notable skills and achievements, such as successful model deployments, A/B tests, or impactful statistical analyses.
Avoid discussing personal career ambitions in this section.
Here’s an example summary from a senior data scientist:
Senior Data Scientist with 10+ years of experience in X and Y industries. Developed a machine learning algorithm that achieved 94% prediction accuracy in global public health applications. Currently seeking to join X company as their next Lead Data Scientist.
And here’s an example from a new graduate:
Recent CS graduate from CMU & Data Scientist with 2 years of experience in Python. Developed pricing models for SaaS products as an intern at a global SaaS HR Services company. Led the university statistics club, growing it to 8 campuses in 6 months.
Work Experience
Focus on your achievements rather than merely listing job duties. Align your accomplishments with the core skills required for the data scientist role you’re targeting.
A “skill: accomplishment” framework will help your resume read like a job description, aligning your skills with most job descriptions.
Showcase your direct impact on key performance indicators (KPIs) such as revenue, growth, or retention.
Here’s an example from a senior data scientist at a large video game company:
Financial Modeling & Data Accuracy: Identified and corrected a flaw in the financial model that overlooked up to 10 million accounts, leading to accurate data capture. Optimized model run time from 3 weeks to 2 days and developed an alternative hypothesis, enhancing overall model reliability.
Data Management & Compliance: Built an audit table that accurately stores financial data linked to the latest Geo-IP history, ensuring precise financial reporting and compliance.
Automation & Reporting: Created automated reports in Tableau, Excel, and FSG, streamlining processes for Tax and Accounting. Translated Hive SQL and Unix Shell Scripts into Python scripts in Databricks, automating workflows and improving efficiency.
Process Improvement & Efficiency: Developed Python scripts that reduced manual work by 500 hours annually, significantly increasing productivity and freeing up resources for higher-value tasks.
Data Analysis & Strategic Insight: Conducted ad-hoc analyses to identify year-over-year trends and explain sales behavior, providing actionable insights that informed strategic decision-making.
Here’s an example from a mid-level data scientist at AT&T:
Propensity Modeling & Customer Targeting: Developed and managed propensity models, improving customer targeting accuracy by 22%, leading to a 15% increase in campaign conversion rates.
Predictive Modeling & Churn Prediction: Implemented speech-to-text models that predicted churn with 85% accuracy across mobile and internet services.
A/B Testing & Customer Engagement: Designed and executed A/B tests that personalized customer interactions, uplifting customer engagement, and increased promotional campaign success rates.
Team Leadership & Project Efficiency: Guided team members and interns, ensuring accurate query logic and model development, contributing to a 25% reduction in project turnaround time.
Past Projects
Highlight projects that demonstrate your technical skills and problem-solving abilities.
Include details like the tools and languages used (e.g., Python, R, TensorFlow) and the outcomes of your work. As you gain more experience, you can streamline this section.
For example, link to a GitHub repository of an open-source project you contributed to.
Technical Skills
Tailor your skills list to the job description, focusing on the languages, frameworks, and workflows that are most relevant. It’s better to highlight fewer skills you are genuinely proficient in than to overstate your abilities.
Common technical skills to include on a data science resume:
Python Data Analysis Frameworks (NumPy, Pandas, Scikit-Learn, Keras)
SQL, MySQL
Data Visualization (Tableau, Excel)
Machine Learning Techniques (supervised and unsupervised learning)
productionizing Models
ℹ️
Review the most common SQL and statistics data science interview questions.
Additionally, map your technical skills to your work experience where applicable so the reader can see how you’ve applied these skills in real-world scenarios.
This also improves searchability on LinkedIn and in applicant tracking systems.
Propensity Modeling & Customer Targeting: Leveraged Python Data Analysis Frameworks (NumPy, Pandas, Scikit-Learn) to develop and manage propensity models, improving customer targeting accuracy by 22%. Applied supervised learning techniques to enhance model precision, leading to a 15% increase in campaign conversion rates.
Predictive Modeling & Churn Prediction: Implemented speech-to-text models using Python and integrated Scikit-Learn for predictive analysis, achieving 85% accuracy in churn prediction across mobile and internet services. Productionized these models, ensuring they were seamlessly deployed into the business pipeline.
A/B Testing & Customer Engagement: Designed and executed A/B tests using SQL and MySQL to analyze customer data and personalize interactions. This approach, combined with machine learning techniques for customer segmentation, increased customer engagement and improved promotional campaign success rates. Utilized Tableau and Excel for clear and compelling data visualization, facilitating decision-making.
Team Leadership & Project Efficiency: Guided team members and interns using SQL and Python to ensure accurate query logic and model development. Mentored the team in best practices for deploying machine learning models, contributing to a 25% reduction in project turnaround time.
If you’re still building your experience, focus on the proactive steps you’ve taken to develop your skills—such as boot camps, courses, or mentorship programs.
Soft Skills
Soft skills are just as important as technical skills in data science. You’ll be expected to work cross-functionally and clearly explain your findings to product managers, data engineers, software engineers, and business leaders. Articulating how you collaborate with others can set you apart, especially for mid-career to senior-career level roles.
Highlight key soft skills in your work experience:
Communication: Ability to convey complex information clearly to non-technical stakeholders.
Critical Thinking: Ability to analyze data objectively and challenge assumptions.
Creativity: Ability to approach problems with unique solutions, often filling in the blanks of missing data.
Here’s an example:
Stakeholder Communication: Primary point of contact for the senior leadership team; presented performance results, development milestones, and new use cases throughout the development cycle.
Education and Certifications
Education and certifications are particularly important in data science. List your degree(s), relevant coursework, and data science or machine learning certifications.
You can include details like relevant projects or internships if you're a recent graduate. For those transitioning from other fields, consider condensing the education segment to emphasize the qualifications most applicable to data science.
Resume Customization
Customizing your resume for each job application is essential. By tailoring your resume to reflect the nuances of the position and the company’s culture, you demonstrate that you’ve thoroughly considered your suitability for the role.
Rework your resume summary to align your skills, experience, and qualifications with the job you’re applying for. Mapping key skills, technologies, and qualifications across your summary, work experience, and skills section will help create a cohesive narrative highlighting your value to the organization.
Here’s how to structure your summary in 3-5 lines:
Who you are
What you do
What you’re known for (significant career accomplishments)
Example: Led, developed, and launched X product into a new target market, resulting in X% market adoption rate and $XXX revenue.
Where you’re going next (target role - function and/or industry)
Example:
Data Scientist with a strong track record of leveraging advanced statistical techniques and machine learning to drive strategic decision-making and business outcomes at scale. At Pinterest, I spearheaded data initiatives that enhanced product marketing, reducing user churn by 21%. I seek to apply my expertise in a forward-thinking organization, aiming to lead data-driven innovations in the tech industry.
Customize your past employment descriptions by emphasizing projects or tasks directly relevant to your target role. For example, if expertise with ETL tools is required, prominently feature any experience developing ETL pipelines. Use the Task-Action-Result framework to build out your resume bullets.
Additional Sections
Enhance your resume by including sections like:
Publications: Highlight your research contributions.
Presentations: Show your ability to communicate complex topics.
Awards: Demonstrate industry recognition.
Professional Affiliations: Indicate active involvement in the data science community.
Including these sections can help demonstrate your expertise and commitment to the field.
Don’t overlook a section on blog posts. These entries can reflect your active interest and ongoing dialogue about current trends or discussions relevant to data science. Optimize these segments based on their alignment with the target job requirements and your vocational experiences.
FAQs
How long should a data science resume be?
The length of your resume depends on your work experience. A data science resume should typically be one page for up to 5 years of experience. If you have 10+ years of experience, you can expand your resume to two pages. Even experienced professionals should focus on the most relevant details.
What are the key elements of a data science resume?
A data science resume should feature your contact information, a summary, relevant work experience, projects, key skills, and educational background.
How should I format my data science resume?
Maintain a clean and professional design. A single column is preferred. Use easy-to-read fonts, incorporate sufficient white space for clarity, and use bullet points for better legibility.
Why is it important to customize my resume for each application?
Tailoring your resume to each job shows that you’ve focused on the role’s nuances and demonstrates your commitment, increasing your chances of capturing the hiring manager’s attention.
What additional sections can enhance my data science resume?
Enhance your resume with sections for publications, presentations, awards, professional affiliations, and blog posts. These additions can showcase your research, communication skills, and active participation in the industry, reinforcing your expertise and commitment to the field.